
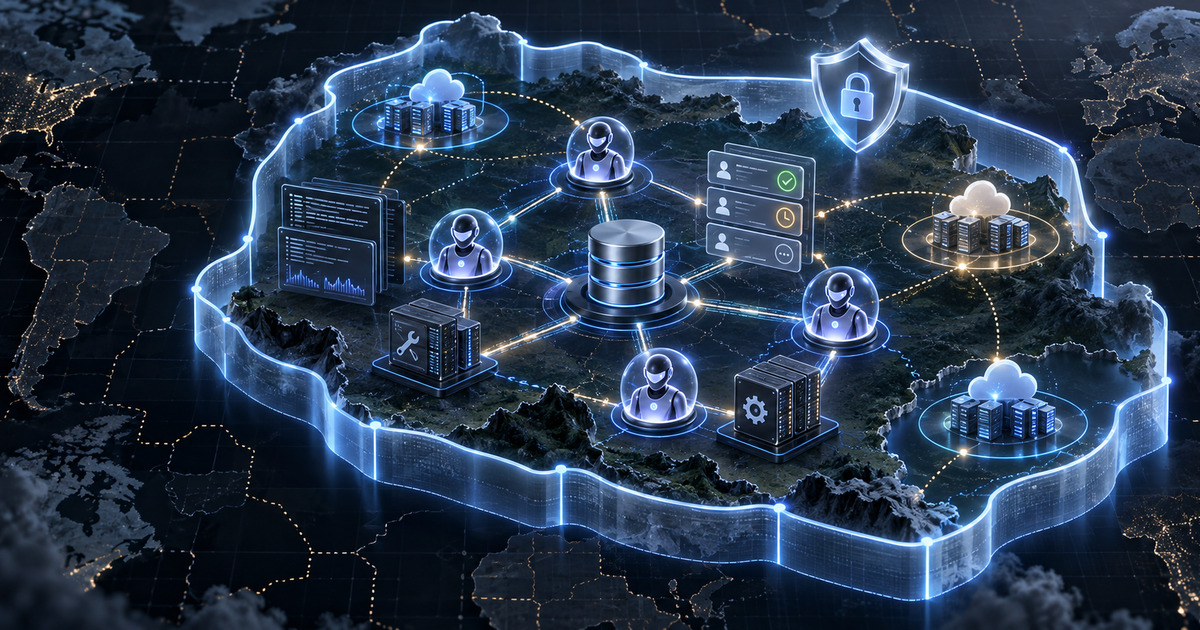
The easiest way to oversimplify AI data residency is to reduce it to a dropdown. Pick a cloud region. Deploy the model endpoint there. Tell the customer the system is “in region.” For a basic API call, that may be the beginning of the answer. For an AI agent, it is nowhere near enough.
Agents do not just send a prompt to a model and return a paragraph. A useful enterprise agent retrieves documents, opens tickets, calls internal APIs, uses external tools, stores intermediate state, asks for approvals, writes traces, and sometimes resumes hours later. Each one of those steps can move regulated, contractual, or customer-confidential data into a new system. If the only residency control is the model endpoint, the real data boundary is probably being set by accident.
The better pattern is a data residency envelope: a policy object that travels with the agent run from start to finish. It says what data class is involved, which jurisdictions are allowed, which systems may process it, what retention mode applies, where traces may be stored, and what the agent must do when a tool cannot satisfy those constraints. In mature systems, the envelope is not a PDF attached to procurement. It is runtime infrastructure.
Cloud providers are already signaling why this matters. Microsoft’s Azure OpenAI documentation discusses data processing, data residency principles, deployment types, prompts and completions, and responsible AI handling. Google’s Gemini Enterprise Agent Platform documentation points operators toward data residency, endpoint locations, supported locations, zero data retention, security controls, and shared responsibility. The details differ by vendor and feature, but the strategic message is consistent: AI systems now have data-governance surfaces that must be configured intentionally. A region setting is a component-level choice, not a complete agent assurance story.
The problem becomes sharper when tools enter the loop. A model call may stay in the selected region while the agent’s next action sends a customer record to a remote tool server, exports a document to a workflow platform, or writes a replay trace to an observability backend. The user experiences one assistant. The architecture experiences a chain of processors.
That is why protocol boundaries matter. The Model Context Protocol authorization specification is useful here because it treats access to tools and resources as a first-class authorization problem. It describes resource parameters, token audience validation, secure token storage, short-lived access tokens, HTTPS requirements, and token-theft risks. Those controls are usually discussed as security mechanics, but they are also residency mechanics. A token issued for one resource, one audience, and one scope is a natural place to attach jurisdiction and retention constraints. A tool that cannot prove its audience, resource, location, or storage behavior should not receive protected data merely because the model decided to call it.
A residency envelope should therefore be evaluated at every transition. Before retrieval, can this index serve the requested tenant’s geography? Before tool execution, is the tool allowed for this data class and jurisdiction? Before logging, can the trace sink store prompts, completions, arguments, and outputs under the right retention policy? Before human review, is the approval queue itself in an approved environment? Before replay or evaluation, has sensitive data been redacted, localized, or excluded?
This is where observability stops being an afterthought. OpenTelemetry’s Generative AI semantic conventions show that the industry is moving toward standard ways to describe AI model and agent activity in traces, logs, and metrics. That matters because residency cannot be governed if the run is invisible. An enterprise should be able to answer: which model endpoint was used, which tools were called, where the tool servers lived, what data classes passed through, what was retained, which policy allowed it, and where the run failed closed.
The NIST AI Risk Management Framework gives the broader governance frame. AI risk is not handled once at launch; it is governed, mapped, measured, and managed across the lifecycle. For agents, data residency belongs in that lifecycle discipline. It should appear in architecture reviews, procurement checks, runtime policy, audit evidence, incident response, and customer commitments. If a team cannot map the agent’s data path, it cannot credibly claim to manage the residency risk.
Practically, the implementation can be straightforward.
First, classify the run before execution. The agent should know whether it is handling public content, internal operational data, customer confidential data, health information, financial records, or another protected class. That classification should determine the allowed residency envelope.
Second, maintain a registry of model endpoints, retrieval systems, tools, queues, trace sinks, and approval surfaces. Each entry should declare supported regions, retention behavior, subprocessors where relevant, and whether prompt or output data may be stored. Do not let agents discover production tools that are not in the registry.
Third, bind authorization to the envelope. Tool credentials should be scoped not only by capability, but also by data class, tenant, geography, and retention mode. Short-lived, audience-bound credentials are easier to revoke and easier to reason about than broad service accounts.
Fourth, instrument the run. Emit trace attributes that let operators reconstruct the residency path without dumping sensitive payloads into logs. The goal is evidence, not surveillance. You need enough metadata to prove that the agent stayed inside its boundary and enough failure records to explain when it did not.
Fifth, fail closed. If a tool has no location metadata, if a trace sink cannot honor the retention mode, if a retrieval index crosses tenants, or if an approval workflow leaves the allowed environment, the agent should stop and escalate. A graceful refusal is cheaper than an invisible cross-border data leak.
The point is not to make agents slower or bury builders in compliance theater. The point is to make autonomy deployable. Enterprises will not trust agents with consequential workflows if nobody can say where the data went. The teams that solve this will not describe residency as a legal checkbox. They will treat it as an execution contract: carried by every run, checked at every boundary, and proven after the fact.
That is the difference between an AI feature that demos well and an AI system that can survive enterprise scrutiny. The region setting still matters. It just needs an envelope around it.
Build AI Systems That Survive Contact With Real Work
We help teams turn AI research into practical automations, agent workflows, and operational systems that can be evaluated and improved.
Get the Field Guide — $10 →